An alert fires at three in the morning: the checkout service's error rate has increased. The chart shows that something broke, but not which request, which customer, or which line of code is responsible. Traceability with Loki and VictoriaMetrics is the practice of connecting these two ends: starting with an aggregated metric and reaching, without guesswork, the log lines for the requests that caused the problem.
In this guide, you will build this bridge with three open source components: VictoriaMetrics for metrics, Loki for logs, and Grafana Alloy as a single collector. The key is not any one tool in isolation, but a simple contract: the same labels and the same request identifier on both sides.
Why metrics and logs alone are not enough
Metrics are inexpensive and fast. A series such as http_requests_total{service="checkout", code="500"} answers, in milliseconds, how many requests failed in the last five minutes. But it is aggregated by nature: it knows nothing about a specific request.
Logs are the opposite. Each line tells the story of an event, with details, but searching for "the right error" across millions of lines without a starting point is slow and frustrating.
Traceability emerges when you can ask the question in both directions:
- From the metric to the log: "This spike in checkout 500 errors between 03:02 and 03:07— which requests did it come from?"
- From the log to the metric: "Is this database timeout an isolated case, or is it part of a trend?"
For that to work, metrics and logs need to speak the same language.
The contract: common labels and a per-request identifier
Before configuring any tool, agree on a minimum contract with the team. It has two parts.
1. Low-cardinality labels that are identical on both sides. Choose a small number of labels that identify where the data came from, and use exactly the same names and values in metrics and logs:
| Label | Example | Purpose |
|---|---|---|
service |
checkout |
Which application |
env |
prod |
Which environment |
instance |
checkout-7f9c |
Which replica or host |
If the metric says service="checkout" and the log says app="Checkout", the bridge breaks. Standardize the names once and apply them in the collector, not in every application.
2. A trace_id in every log line. Each request receives a unique identifier when it enters the system, and that identifier is propagated to subsequent services. The W3C Trace Context standard (the traceparent header) already solves this, and OpenTelemetry libraries propagate it automatically. The application only needs to write this identifier to the logs, preferably in JSON:
{"ts":"2026-11-02T03:04:11Z","level":"error","service":"checkout","trace_id":"4bf92f3577b34da6a3ce929d0e0e4736","msg":"payment gateway timeout","duration_ms":5003}
Notice the difference in roles: service is a label (with few possible values), while trace_id is line data (one value per request). This distinction is what keeps Loki fast, as you will see next.
Traceability with Loki and VictoriaMetrics in practice
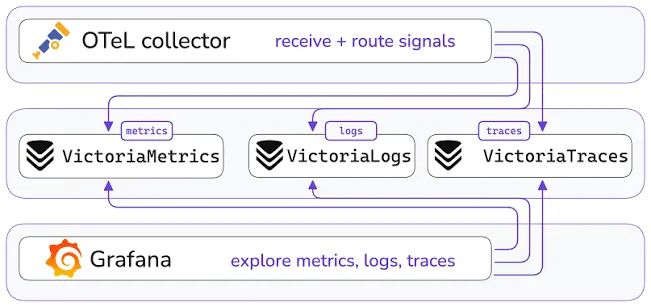
The architecture looks like this: the application exposes metrics in Prometheus format and writes logs in JSON. Alloy collects both, applies the label contract, and sends metrics to VictoriaMetrics (via remote write) and logs to Loki. Grafana queries both.
Metrics in VictoriaMetrics
VictoriaMetrics is compatible with the Prometheus ecosystem: it accepts remote write, understands PromQL, and offers MetricsQL, a superset with additional functions. In Alloy, collection and forwarding look like this:
prometheus.scrape "checkout" {
  targets = [{
    "__address__" = "checkout:8080",
    "service"     = "checkout",
    "env"         = "prod",
  }]
  forward_to = [prometheus.remote_write.victoria.receiver]
}

prometheus.remote_write "victoria" {
  endpoint {
    url = "http://victoriametrics:8428/api/v1/write"
  }
}
With this in place, the error rate by service is a direct query:
sum by (service) (rate(http_requests_total{env="prod", code=~"5.."}[5m]))
Logs in Loki, with trace_id in the right place
Loki indexes only the labels for each log stream; the line content is not indexed. For that reason, putting trace_id in a label would be a classic mistake: each request would create a new stream, cardinality would explode, and Loki would become slow and expensive.
The right place is structured metadata, available in Loki 3: a field attached to the line that can be filtered in queries but remains outside the stream index. In Alloy:
loki.process "checkout" {
  stage.json {
    expressions = { trace_id = "trace_id", level = "level" }
  }
  stage.labels {
    values = { level = "" }
  }
  stage.structured_metadata {
    values = { trace_id = "" }
  }
  stage.static_labels {
    values = { service = "checkout", env = "prod" }
  }
  forward_to = [loki.write.default.receiver]
}

loki.write "default" {
  endpoint {
    url = "http://loki:3100/loki/api/v1/push"
  }
}
Notice that service and env have the same names and values used in the metrics. This is where the contract becomes configuration.
From the chart spike to the log line
With everything in place, investigating the three-in-the-morning alert becomes a short process:
- In the metrics dashboard, the error query shows a spike for
service="checkout"between 03:02 and 03:07. - In Grafana Explore, with Loki as the data source and the same time range, filter using the same labels:
logql
   {service="checkout", env="prod", level="error"} | json
- One line stands out:
payment gateway timeout. It contains thetrace_id. Now filter by it, without needing to index it:
logql
   {env="prod"} | trace_id="4bf92f3577b34da6a3ce929d0e0e4736"
The query returns every line from that request, across all the services it passed through, in order. That is traceability in practice: the complete story of a request.
- Back in the metrics, confirm whether the problem is systemic. Did gateway latency increase for everyone, or only for this request?
promql
   histogram_quantile(0.99, sum by (le) (rate(gateway_request_duration_seconds_bucket{service="checkout"}[5m])))
To shorten the path even further, configure a data link in Grafana on the metrics dashboards that opens Loki Explore with the same labels and time range. And if you also store traces in a dedicated backend, use the Loki data source's derived fields to turn each line's trace_id into a clickable link to the trace.
Alerts that already point to the logs
The final step is to make the alert carry the bridge with it. With vmalert (the VictoriaMetrics rule evaluator), the rule's annotations can include the log query already prepared:
groups:
  - name: checkout
    rules:
      - alert: CheckoutErrorRateHigh
        expr: sum(rate(http_requests_total{service="checkout", env="prod", code=~"5.."}[5m])) > 1
        for: 5m
        labels:
          severity: page
        annotations:
          summary: "Erros 5xx elevados no checkout"
          logs: '{service="checkout", env="prod", level="error"} | json'
Whoever receives the alert already knows where to start, without having to build the query in a hurry.
Common pitfalls
- Diverging labels.
serviceon one side andappon the other. Standardize them in the collector and review them whenever a new service is added. trace_idas a Loki label. This causes cardinality to explode. Use structured metadata, or leave the field in the JSON and extract it with| json.- Logs without
trace_idalong part of the path. A single service that fails to propagatetraceparentis enough to leave the story incomplete. Treat propagation as a requirement, not a detail. - Misaligned clocks. If hosts do not synchronize their time (NTP), the chart's time window will not match the logs'.
- High-cardinality labels in metrics. Putting a user or order identifier in a metric is the same mistake as putting
trace_idin Loki, only in VictoriaMetrics. This data belongs in logs.
Next steps
Start small: choose a critical service, apply the label contract, ensure that trace_id is present in the logs, and build the "from chart to log line" process for a real alert. Once it works end to end, replicate the pattern across the other services. The most important tool for this traceability is neither Loki nor VictoriaMetrics: it is the contract that makes them communicate.